TL;DR
- What this is: an end-to-end workflow for producing TikTok/Reels-style vertical clips with seedance-2.0-mini on the hiapi API — from the first curl call to a batch script that renders a week of content. The demo clips on this page were generated with the exact requests shown.
- Why this model for short-form: native
9:16support, built-in synced audio (no separate sound pass), flexible 4–15 s durations, and 480p drafts at $0.068/second — a 4-second vertical draft costs about $0.27 (pricing). - Verified API facts:
prompt,duration(integer 4–15), andresolution(480p|720p) are required;aspect_ratioaccepts1:1,4:3,3:4,16:9,9:16,21:9,adaptive. Image-to-video usesfirst_frame_url/last_frame_url. The schema is strict — unknown fields likeseedare rejected with a 400. - Workflow: generate at 480p to iterate on prompts, re-render keepers at 720p, and batch-submit tasks in parallel — the async
/v1/tasksqueue does the fan-out for you.
Why seedance-2.0-mini fits the short-form loop
Short-form production is volume work: you draft many clips, keep a few, and post daily. That workflow needs three things from a video API — cheap iterations, vertical output, and sound — and seedance-2.0-mini happens to check all three:
- Cost per draft is low enough to iterate. At 480p the model bills $0.068 per second of output, so a 4-second draft is ~$0.27 and even a full 15-second clip stays close to $1. The 720p tier is $0.147/s. (Prices verified against the live pricing page; video is billed per second, so
durationis your cost lever.) - Native 9:16. You render vertical directly instead of cropping a landscape clip and losing the composition.
- Native synced audio. Output MP4s ship with an AAC audio track generated with the scene — ambience, foley, room tone. For feed content that autoplays with sound, this saves an entire editing step.
If you want the bigger sibling for hero content, the same workflow applies to seedance-2-0 — only the price tier changes.
Setup
You need an hiapi API key and nothing else — no SDK. Keep the key in an env var:
export HIAPI_API_KEY="sk-..."
All video models on hiapi run through the unified async task endpoint: POST https://api.hiapi.ai/v1/tasks returns a taskId immediately, and you poll GET /v1/tasks/{taskId} until it finishes. Details are in the docs.
Your first vertical clip (T2V)
The smallest valid request needs prompt, duration, and resolution. Add aspect_ratio: "9:16" for short-form:
curl -X POST https://api.hiapi.ai/v1/tasks \
  -H "Authorization: Bearer $HIAPI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "seedance-2.0-mini",
    "input": {
      "prompt": "Vertical short-form video. A fresh matcha latte being poured in slow motion into a clear glass on a sunlit cafe counter, green swirls blooming through the milk, soft window light, shallow depth of field. Native audio: gentle cafe ambience, liquid pouring. Crisp, appetizing, photoreal.",
      "duration": 4,
      "resolution": "480p",
      "aspect_ratio": "9:16"
    }
  }'
The response is instant:
{"code": 200, "data": {"taskId": "tk-hiapi-01KWTTFDPHSDWZ0FP1QAS5J79Q"}, "message": "success"}
Poll the task until status is success, then download output[0].url right away — output URLs are temporary and expire. Here is the actual clip that exact request produced (4 s, 480p, 9:16, with native pour-and-ambience audio — unmute to hear it):
Two practical notes from this render: the "480p" vertical output measures 496×864 pixels, and the audio arrived as a proper AAC track in the MP4 — no separate file to mux.
The input schema, verified against the live API
The schema is strict. These are real validation responses, reproduced verbatim, so you can recognize them when they hit your logs:
| Field | Type | Required | Values |
|---|---|---|---|
prompt | string | ✅ (min length 3) | your shot description |
duration | integer | ✅ | 4–15 (seconds) |
resolution | string | ✅ | 480p, 720p |
aspect_ratio | string | optional | 1:1, 4:3, 3:4, 16:9, 9:16, 21:9, adaptive |
first_frame_url | string | optional | image URL for I2V start frame |
last_frame_url | string | optional | image URL for end-frame control |
image_input | array | optional | multimodal image references |
reference_video_urls | array | optional | style/motion reference videos (cheaper per-second rate) |
Omit a required field and the task is rejected before it's created (no charge):
{"code": 400, "error_code": "INVALID_REQUEST", "message": "invalid input: resolution: missing required field \"resolution\"; duration: missing required field \"duration\""}
Out-of-range values name the exact bounds — duration: maximum: got 16, want 15 — and unknown fields are refused rather than ignored:
{"code": 400, "error_code": "INVALID_REQUEST", "message": "invalid input: <root>: additional properties 'seed' not allowed"}
That last behavior is worth internalizing: if you carry request shapes over from another model (a seed, a size, an audio flag), seedance-2.0-mini will 400 instead of silently dropping the field.
A reusable Python function
Everything you need for production is ~40 lines — submit, poll, download:
import os, time, requests

API = "https://api.hiapi.ai/v1/tasks"
HEADERS = {"Authorization": f"Bearer {os.environ['HIAPI_API_KEY']}"}

def submit(prompt: str, duration: int = 4, resolution: str = "480p",
           aspect_ratio: str = "9:16", **extra) -> str:
    r = requests.post(API, headers=HEADERS, json={
        "model": "seedance-2.0-mini",
        "input": {"prompt": prompt, "duration": duration,
                  "resolution": resolution, "aspect_ratio": aspect_ratio, **extra},
    }, timeout=60)
    data = r.json()
    task_id = (data.get("data") or {}).get("taskId")
    if not task_id:
        raise RuntimeError(f"submit failed: {data}")
    return task_id

def wait(task_id: str, timeout_s: int = 900) -> dict:
    deadline = time.time() + timeout_s
    while time.time() < deadline:
        task = requests.get(f"{API}/{task_id}", headers=HEADERS, timeout=30).json()["data"]
        if task["status"] == "success":
            return task
        if task["status"] == "fail":
            raise RuntimeError(f"task failed: {task.get('error')}")
        time.sleep(8)
    raise TimeoutError(task_id)

def make_clip(prompt: str, out_path: str, **kw):
    task = wait(submit(prompt, **kw))
    url = task["output"][0]["url"]          # temporary URL — download immediately
    with open(out_path, "wb") as f:
        f.write(requests.get(url, timeout=120).content)
A 4-second 480p clip typically finishes in a couple of minutes; budget up to ~10 minutes at peak times before calling it a timeout.
Image-to-video: lock the first frame
For product-led shorts, prompt drift is the enemy — you want your product in frame, not the model's idea of it. The fix is I2V with first_frame_url: generate (or photograph) a still, then animate it. A vertical reference still like this one, made with gpt-image-2 through the same /v1/tasks endpoint, works well as a start frame:
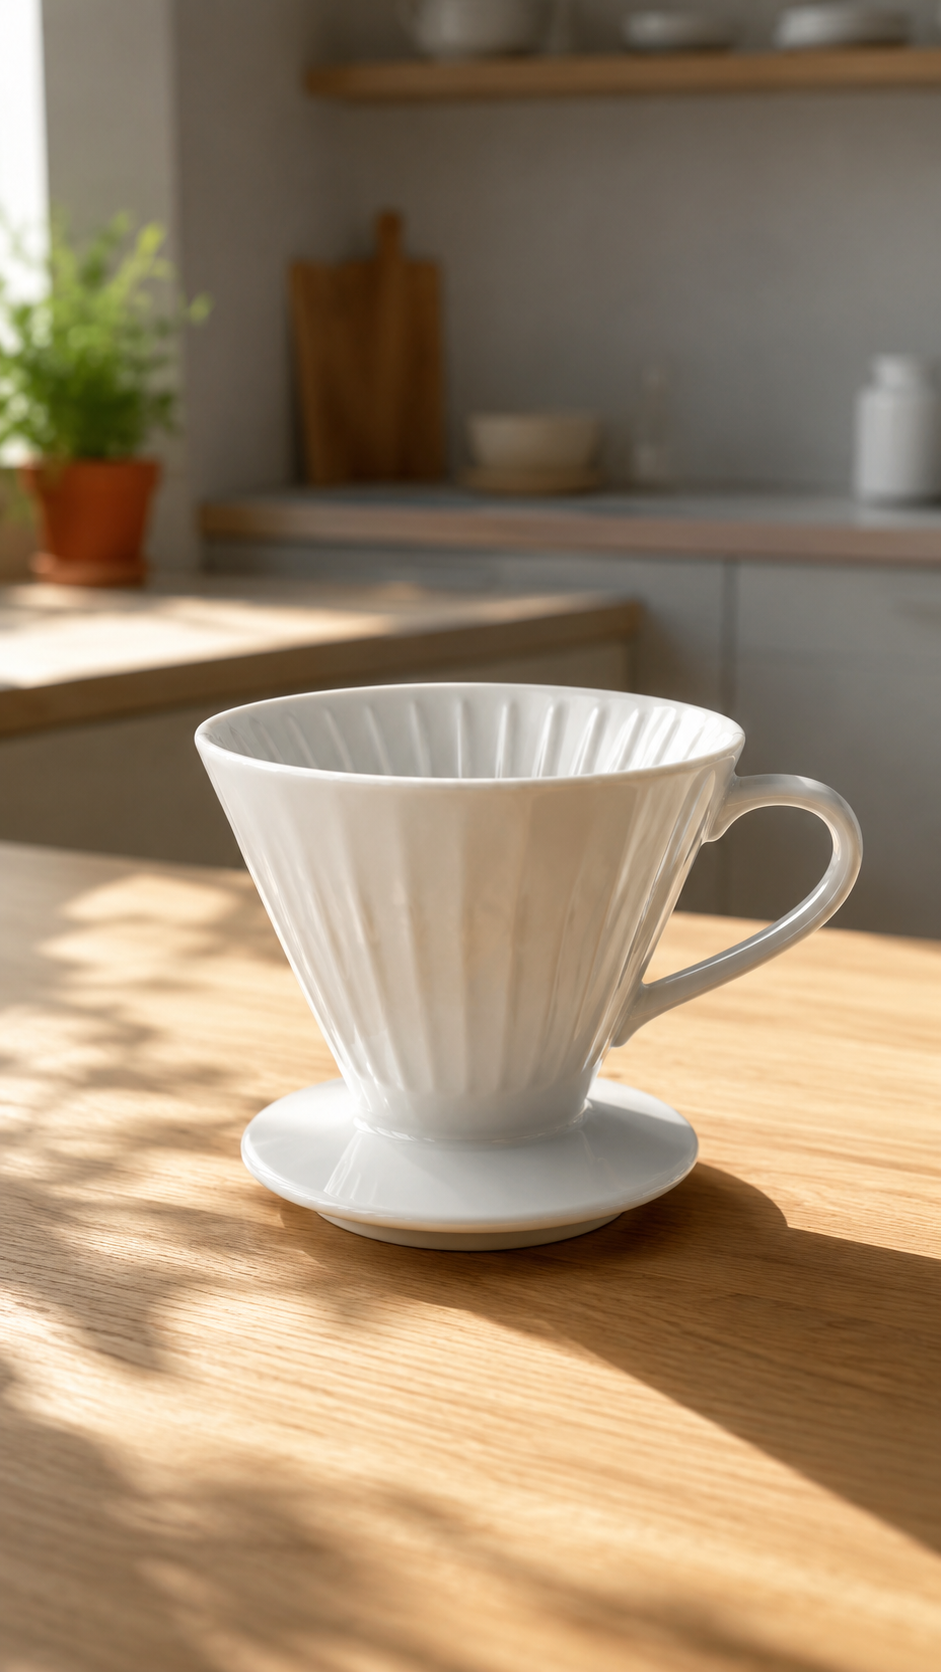
The request just adds one field:
task_id = submit(
    "Steam begins to rise from the pour-over dripper as hot water is poured "
    "in a slow circle from above, droplets falling into the glass carafe below, "
    "sunlight catching the steam. Slow gentle push-in. "
    "Native audio: soft water trickle, quiet morning room tone.",
    duration=4, resolution="480p", aspect_ratio="9:16",
    first_frame_url="https://your-cdn.example/pourover-ref.jpg",
)
Here's what first-frame animation delivers in practice — a still from our seedance-2.0-mini recipe library and the clip it became, same model and request shape (16:9 in this example):
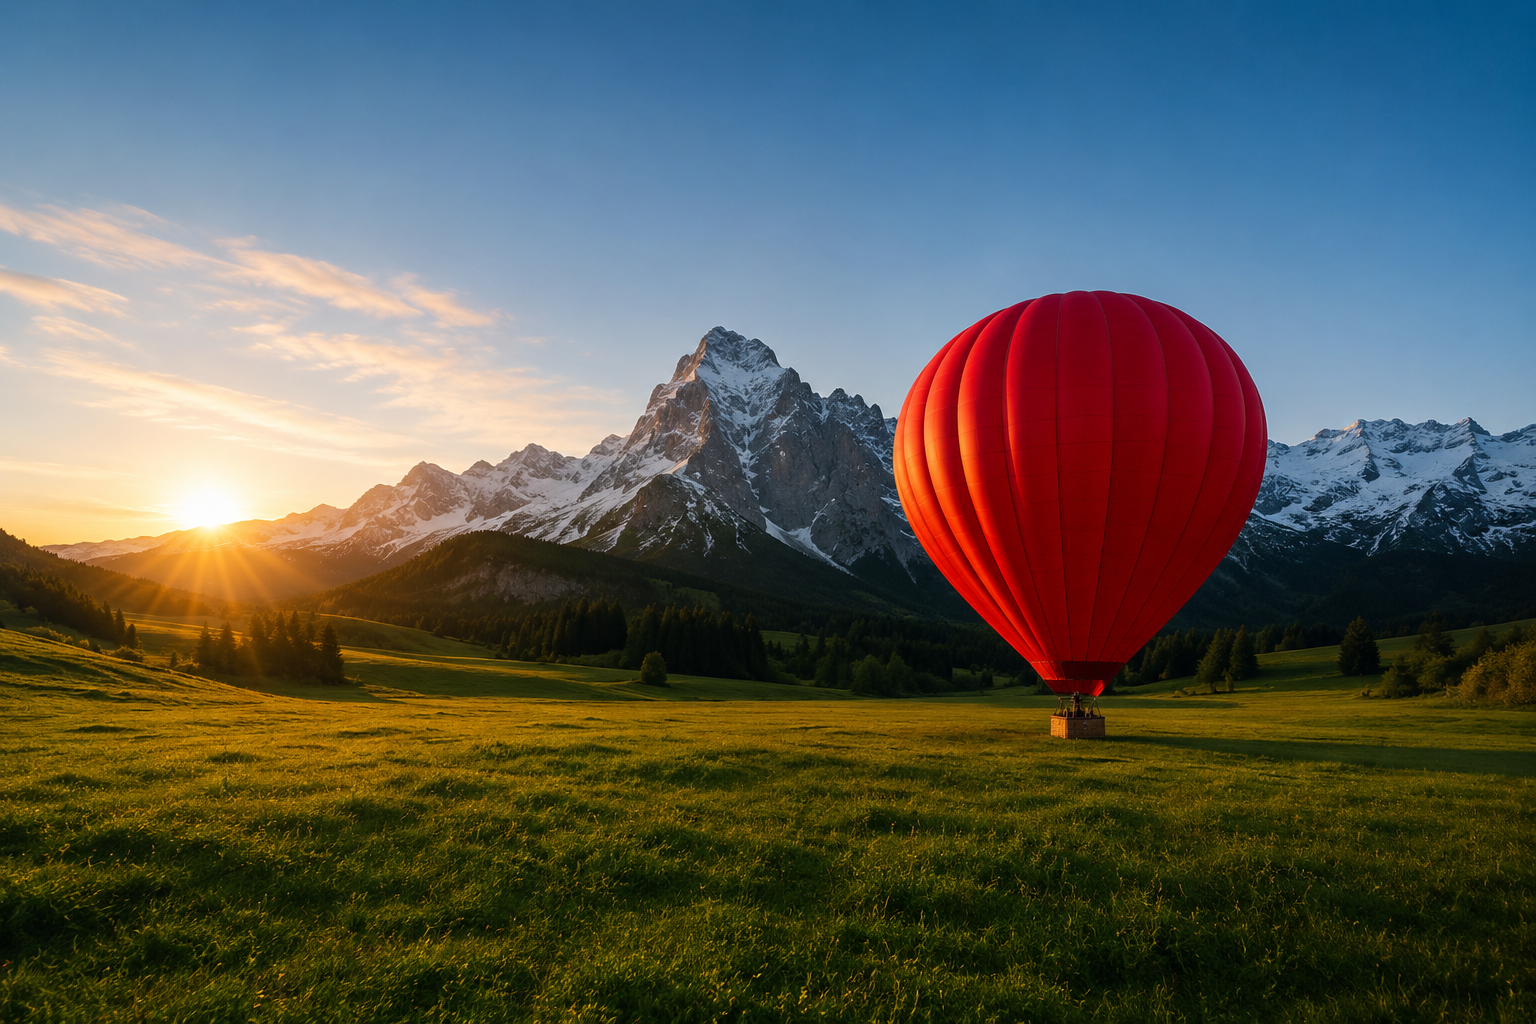
The composition, palette, and subject stay locked to your still; the prompt only has to describe the motion. There's also last_frame_url if you need the clip to land on a specific end frame — useful for loops that cut back to a product card.
Batching a week of content
Because /v1/tasks is async, batch production is just: submit everything, then poll. No client-side queue needed.
briefs = [
    ("mon-hook",  "Vertical clip. Espresso shot pulling in slow motion, ..."),
    ("tue-loop",  "Vertical seamless-loop clip. Steam curling off a cup, ..."),
    ("wed-recipe","Vertical clip. Overhead pour-over brewing sequence, ..."),
    # ... one per posting day
]

tasks = {name: submit(p, duration=6) for name, p in briefs}   # fan out
for name, tid in tasks.items():                                 # collect
    make = wait(tid)
    url = make["output"][0]["url"]
    open(f"{name}.mp4", "wb").write(requests.get(url, timeout=120).content)
The cost math stays predictable because billing is per output second:
| Plan | Spec | Cost |
|---|---|---|
| 1 draft iteration | 4 s · 480p | ~$0.27 |
| 1 posting-ready clip | 6 s · 480p | ~$0.41 |
| 7 clips (a week, daily) | 7 × 6 s · 480p | ~$2.86 |
| Hero re-render | 6 s · 720p | ~$0.88 |
A workflow that holds up well: draft every idea at 480p, keep the winners, re-render only those at 720p. For more levers (resolution tiers, duration trimming, batch scheduling), see our guide to controlling AI image and video API costs.
Prompting for the feed
What worked across our test renders, tuned for short-form specifically:
- Say "vertical" and compose for it. Leading with "Vertical short-form video." plus
aspect_ratio: "9:16"keeps subjects centered in the tall frame instead of framing a landscape scene that gets cropped. - Put the hook in second one. Feeds decide in the first second — make the very first motion the payoff (the pour already falling, the steam already rising), not a slow establishing move.
- Script the audio. A "Native audio: ..." sentence listing 2–3 concrete sounds (liquid pouring, cafe ambience) reliably shapes the soundtrack. Unprompted, you get generic room tone.
- For loopable clips, minimize start-to-end change. Drifting particles, pulsing glow, curling steam — describe steady-state motion and the first/last frames land close enough to loop.
For a deeper set of tested prompt patterns with side-by-side results — camera moves, styles, action, audio — see the companion piece: seedance-2.0-mini prompt recipes.
Wrap-up
Short-form video production with seedance-2.0-mini comes down to one async endpoint, three required fields, and per-second pricing that makes iteration cheap: draft vertical clips at 480p for about a quarter each, lock product shots with first_frame_url, batch-submit your posting calendar, and re-render keepers at 720p. Grab an API key, then start with the 4-second curl request above — the seedance-2.0-mini model page has the parameter reference and live pricing to take it from there.