TL;DR
- Grok Imagine 1.5 Lite Text to Video (
grok-imagine-1.5-lite/text-to-video) turns one prompt into a 1–15 second video with sound built in, natively in seven aspects including vertical and square. Try it on the model page; new accounts get 200 free credits. - Pricing is per second: 480P $0.029, 720P (default) $0.043, 1080P $0.20 — a 720p 6-second clip is $0.258.
- Everything runs on HiAPI
/v1/tasks: submit for ataskId, poll, then take the video fromoutput(temporary — save it).
What it does
- One paragraph covers picture, motion, and sound: the rig and the sound effects go into the prompt, and the clip ships with its audio track (no off switch, no surcharge).
- 1–15 seconds, any integer:
durationtakes whatever you pass, default 6. - Seven aspects, natively generated: 16:9, 9:16, 1:1, 4:3, 3:2, 2:3, 3:4 — vertical and square aren't crops.
- A sibling animates stills:
grok-imagine-1.5-lite/image-to-videotakes one image — see the image-to-video guide.
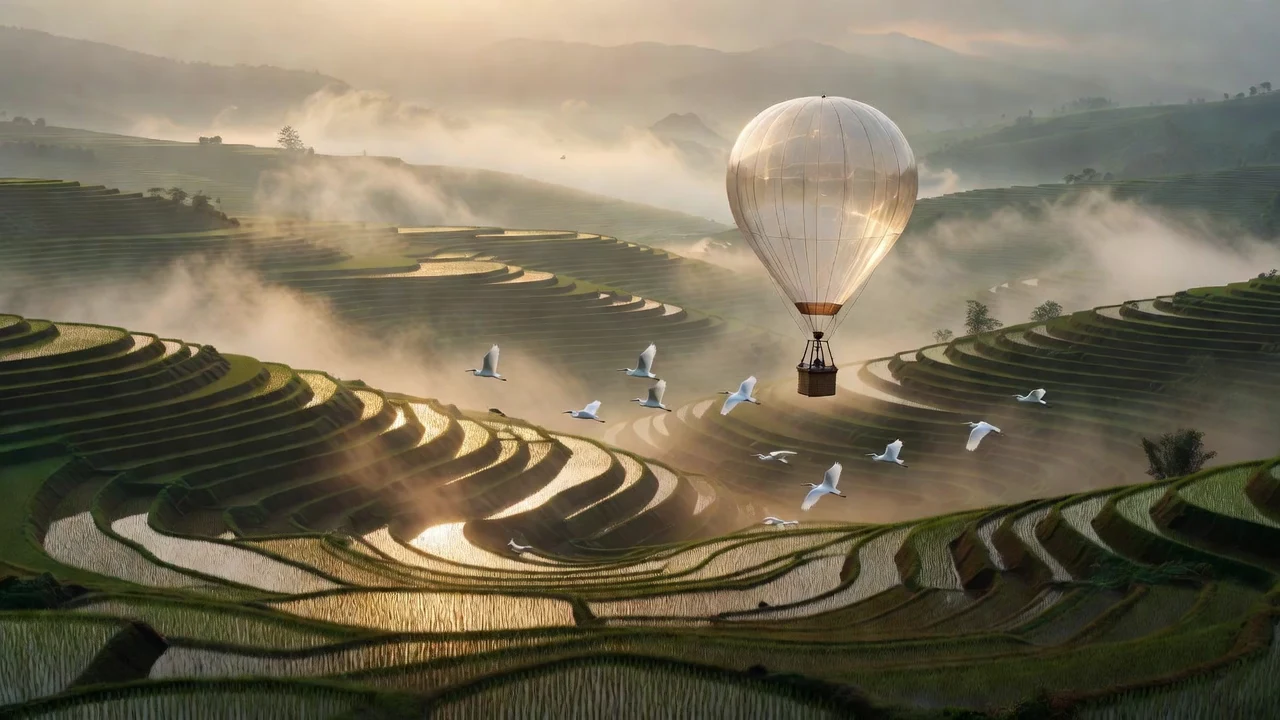
Here's a real clip (720p · 6 s · 16:9, with wind and birdsong):
A glass hot-air balloon drifts slowly over a misty valley of terraced rice fields at sunrise. Golden light spills across the water-filled terraces, mist rolls between the hills, a flock of white egrets glides beneath the balloon. Smooth aerial tracking shot, gentle wind sounds and distant birdsong, cinematic, natural colors. No text, no logos.
grok-imagine-1.5-lite/text-to-video, 720P, 6 s, 16:9, 1280×720, sound included, $0.258. Watch the full clip →
Pricing: three tiers, per second
| Tier | Per second | 5 s | 6 s | 15 s |
|---|---|---|---|---|
| 480P | $0.029 | $0.145 | $0.174 | $0.435 |
| 720P (default) | $0.043 | $0.215 | $0.258 | $0.645 |
| 1080P | $0.20 | $1.00 | $1.20 | $3.00 |
HiAPI current prices, checked October 23, 2026. Note 1080P at $0.20/s is about 4.65× 720P — draft at 720p and reserve 1080P for finals. Failed tasks refund in full.
Two ways to start
Browser, 3 steps: open the model page → paste the prompt, pick duration, resolution, aspect → generate. A 720p 6-second clip is $0.258.
API, 3 steps: POST /v1/tasks to submit → take the taskId → poll to success.
curl: your first clip
curl -X POST https://api.hiapi.ai/v1/tasks \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Idempotency-Key: your-unique-key-001" \
  -d '{
  "model": "grok-imagine-1.5-lite/text-to-video",
  "input": {
    "prompt": "A glass hot-air balloon drifts slowly over a misty valley of terraced rice fields at sunrise. Golden light spills across the water-filled terraces, mist rolls between the hills, a flock of white egrets glides beneath the balloon. Smooth aerial tracking shot, gentle wind sounds and distant birdsong, cinematic, natural colors. No text, no logos.",
    "duration": 6,
    "resolution": "720p",
    "aspect_ratio": "16:9"
  }
}'
Python: submit, poll, download
import time, uuid, requests

BASE = "https://api.hiapi.ai/v1/tasks"
HEADERS = {
    "Authorization": "Bearer YOUR_API_KEY",
    "Content-Type": "application/json",
}

payload = {
    "model": "grok-imagine-1.5-lite/text-to-video",
    "input": {
        "prompt": "A glass hot-air balloon drifts slowly over a misty valley of terraced rice fields at sunrise. Golden light spills across the water-filled terraces, mist rolls between the hills, a flock of white egrets glides beneath the balloon. Smooth aerial tracking shot, gentle wind sounds and distant birdsong, cinematic, natural colors. No text, no logos.",
        "duration": 6,
        "resolution": "720p",
        "aspect_ratio": "16:9",
    },
}

resp = requests.post(
    BASE,
    headers={**HEADERS, "Idempotency-Key": str(uuid.uuid4())},
    json=payload,
    timeout=30,
)
resp.raise_for_status()
task_id = resp.json()["taskId"]

while True:
    task = requests.get(f"{BASE}/{task_id}", headers=HEADERS, timeout=30).json()
    print(task["status"])
    if task["status"] in ("success", "fail"):
        break
    time.sleep(5)

if task["status"] == "success":
    video = next(o for o in task["output"] if o.get("type") == "video")
    mp4 = requests.get(video["url"], timeout=120)   # temporary URL — save promptly
    with open("output.mp4", "wb") as f:
        f.write(mp4.content)
    print("saved output.mp4")
Parameters
| Field | Required | Values | Notes |
|---|---|---|---|
prompt | yes | 1–4,096 chars | Picture, motion, camera, and sound in one go |
duration | no | any integer 1–15, default 6 | Unlike enumerated-duration models |
resolution | no | 480p / 720p / 1080p, default 720p | 1080P at $0.20/s — watch the bill |
aspect_ratio | no | 7 options, default 16:9 | Vertical and square are native |
Any field outside the table returns a 400.
Errors you'll actually hit
| Status | Meaning | What to do |
|---|---|---|
| 400 INVALID_REQUEST | Malformed body (missing prompt, duration of 0 or 16, unknown fields) | Fix the payload against the table |
| 402 INSUFFICIENT_QUOTA | Out of credits (no charge) | Top up and retry |
| 429 RATE_LIMITED | Rate limited | Slow your submissions |
| 409 / 422 IDEMPOTENCY_KEY_* | Same idempotency key resubmitted | Generate a fresh key |
Terminal failures use CONTENT_POLICY_VIOLATION, TASK_FAILED, and TASK_TIMEOUT; failed tasks refund in full.
Before you ship
- Callbacks: video tasks run long — pass
"callback": {"url": "https://..."}and skip polling. - Persist outputs: the video URL in
outputis temporary; download immediately. - Sound can't be disabled: strip the track in post if you need silence; the price is the same.
- 1080P in bulk adds up: $1.20 a 6-second clip; explore at 480P ($0.174) instead.
FAQ
- Yes, every clip ships with sound: describe the effects (wind, birdsong, spoken lines) and they generate with the picture; there's no off switch.
- Yes, duration is any integer 1–15, not fixed steps.
- Yes, vertical and square are native, not crops — the composition is as complete as landscape.
- Yes, $10 buys about 38 clips: $0.258 each at 720P, 6 seconds.
- Yes, all three tiers support all seven aspect ratios — resolution only affects sharpness, not which ratios are available.
- Yes, characters can speak: quote the line in the prompt (see the baker example) and dialogue arrives with the ambience.
Next: take the balloon prompt and generate your first clip; you can try the five scene prompts directly on the text-to-video model page.