We timed nine image generation APIs on HiAPI with the same prompt at 1K, three runs each, from submitting the request to having the finished image URL. FLUX.2 Klein 4B was the fastest at about 17 seconds (and the cheapest, at $0.00143 per image), followed by FLUX Schnell, Grok Imagine, and Z-Image at 26–28 seconds. The GPT Image models and Qwen Image 3.0 took one to one and a half minutes, and GPT Image 2 had a 6-minute outlier.
Results
| Model | Median time | Fastest / slowest run | Price per 1K image |
|---|---|---|---|
flux-2-klein-4b/text-to-image (1 MP) | 16.6 s | 16.4 / 17.7 s | $0.00143 |
flux-schnell/text-to-image | 25.6 s | 17.5 / 27.1 s | $0.005 |
grok-imagine/text-to-image | 27.4 s | 27.0 / 47.5 s | $0.03 |
z-image | 27.9 s | 26.4 / 40.9 s | $0.008 |
nano-banana-2 | 53.7 s | 42.7 / 63.9 s | $0.036 ($0.018 on sale) |
gpt-image-2.5-flare/text-to-image | 56.7 s | 52.4 / 70.0 s | $0.05 ($0.025 on sale) |
gpt-image-2/text-to-image@ext (low quality) | 66.9 s | 42.4 / 337.9 s | $0.007 |
gpt-image-2/text-to-image | 74.8 s | 74.4 / 380.9 s | $0.03 |
qwen-image-3.0/text-to-image | 82.3 s | 70.7 / 94.7 s | $0.0358 |
Measured on HiAPI on October 15, 2026: 1:1 at 1K (1 MP for Klein), three rounds, all nine models submitted together in each round. Time runs from the create request to the moment polling (every 2 seconds) saw success, so it includes queueing. "On sale" is the Programmers' Day 50% offer, which runs until November 9, 2026 (UTC+8).
How to read it:
- These are end-to-end times your app actually waits, not GPU time. A single run can be slow because of queueing; that's why GPT Image 2 has a median around 75 seconds but one run of over 6 minutes.
- Three runs in one day is a small sample. Use it to sort models into tiers (under 30 seconds, about a minute, over a minute), not to split hairs between neighbors.
What the images look like
The same prompt on all nine models, first round:
A ceramic coffee mug on a wooden desk next to a laptop, soft morning window light, photorealistic product photo
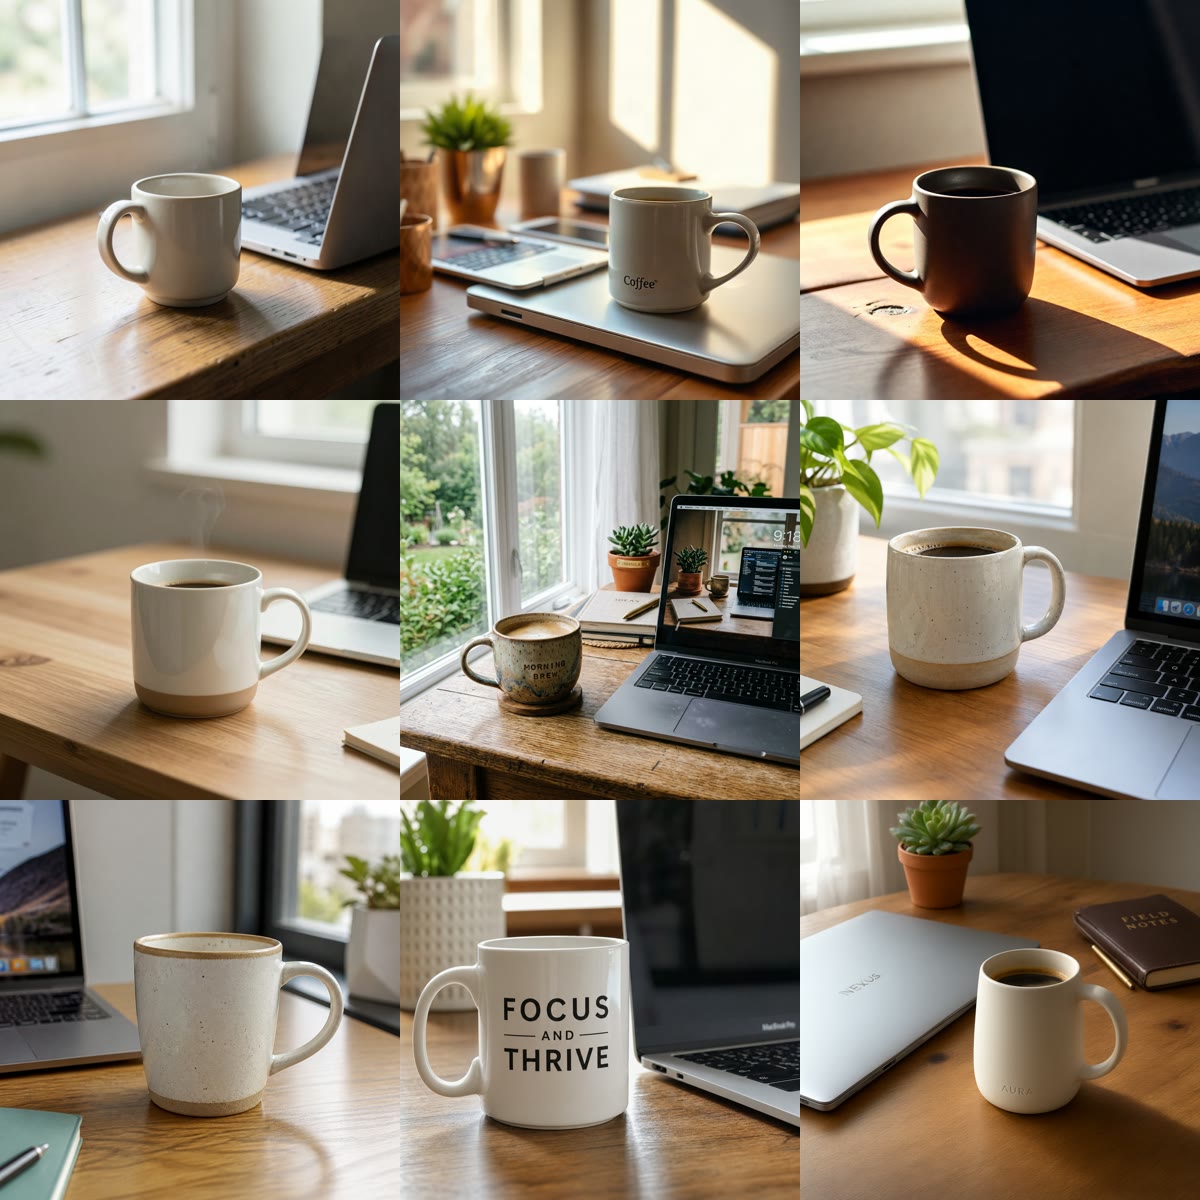
Top row: FLUX.2 Klein 4B, FLUX Schnell, Grok Imagine. Middle row: Z-Image, Nano Banana 2, GPT Image 2.5 Flare. Bottom row: GPT Image 2 (low quality, ext route), GPT Image 2, Qwen Image 3.0. All 1024×1024 except Grok Imagine (960×960).
All nine followed the prompt. The fast tier produces clean, usable product shots. The slower models add more scene detail (plants, notebooks, a window view) and, unprompted, sometimes print text on the mug ("Coffee", "MORNING BREW", "FOCUS AND THRIVE"). If you need a clean mug, add "no text, no logo" to the prompt.
Which one for high-volume workflows
- Thumbnails, drafts, A/B variants at scale: FLUX.2 Klein 4B. Fastest and cheapest in this test: 1,000 images at 1 MP cost $1.43.
- Fast with a bit more polish: FLUX Schnell ($0.005) or Z-Image ($0.008), both under 30 seconds.
- Fast, mid-priced: Grok Imagine ($0.03), about 27 seconds.
- Text in the image, layouts, product marketing: GPT Image 2 or GPT Image 2.5, and plan for a minute or more per image. Run them asynchronously with callbacks instead of making a user wait.
Getting the most speed out of any model
- Don't wait in the request. Submit with
POST /v1/tasks, return to the user, and take the result from a callback ("callback": {"url": "https://your-app.example.com/hiapi/callback"}). - Submit in parallel. Every task is independent, so 50 images submitted together finish in about the time of one round, not 50.
- Set a timeout and a fallback. Given outliers like the 6-minute GPT Image 2 run, give up after a few minutes and resubmit, or fall back to a faster model.
- Stay at 1K for drafts. Higher resolutions cost more and usually take longer.
curl -X POST https://api.hiapi.ai/v1/tasks \
  -H "Authorization: Bearer $HIAPI_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "flux-2-klein-4b/text-to-image",
    "input": {
      "prompt": "A ceramic coffee mug on a wooden desk next to a laptop, soft morning window light, photorealistic product photo",
      "aspect_ratio": "1:1",
      "resolution": "1 MP"
    },
    "callback": {"url": "https://your-app.example.com/hiapi/callback"}
  }'
Every model above uses the same endpoint; only model and the input fields change. Note the small schema differences: Klein takes resolution like "1 MP", Grok Imagine uses lowercase "1k", and Z-Image and FLUX Schnell take only aspect_ratio.
FAQ
What is the fastest image generation API?
In our test on HiAPI, FLUX.2 Klein 4B: a median of 16.6 seconds from request to finished image at 1 MP, with all three runs between 16 and 18 seconds.
Is the fastest model also the cheapest?
Here, yes. FLUX.2 Klein 4B at 1 MP is $0.00143 per image, the lowest price in the test.
Why is GPT Image 2 so much slower?
We can't see inside the model, only the timings: its median was 75 seconds and one run took over 6 minutes. If you use it, design for asynchronous delivery.
Do these times include the network and queue?
Yes. They're measured from our client: request, queue, generation, and up to about 2 seconds of polling delay.
Every model here is on the pricing page. Try the fastest one on the FLUX.2 Klein 4B model page.